Antonin Raffin is a research engineer at the German Aerospace Center (DLR) who specializes in reinforcement learning (RL). He is the lead developer of Stable-Baselines3 (SB3), an open-source library that implements Deep RL algorithms. His main focus is on learning controllers directly on real robots and improving the reproducibility of RL.
Proof of concept version of Stable-Baselines3 in Jax.
Blazingly fast implementation of the Datasaurus paper in Rust. Same Stats, Different Graphs.
A set of improved implementations of reinforcement learning algorithms in PyTorch.
Learning to drive smoothly in minutes using reinforcement learning on a Donkey Car.
A collection of 70+ pre-trained RL agents using Stable Baselines
S-RL Toolbox: Reinforcement Learning (RL) and State Representation Learning (SRL) for Robotics
A fork of OpenAI Baselines, implementations of reinforcement learning algorithms
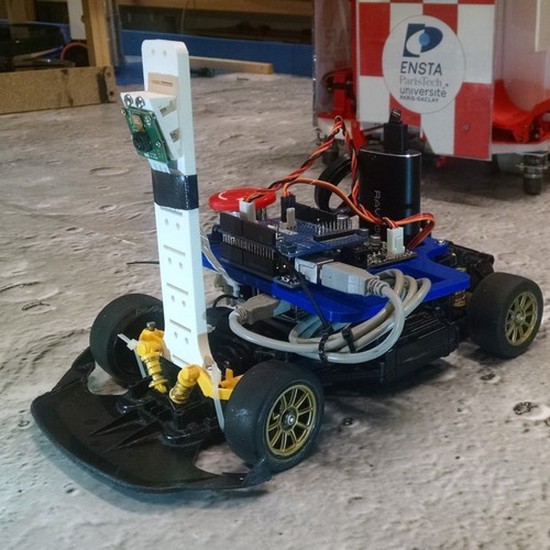
Autonomous Racing Robot With an Arduino, a Raspberry Pi and a Pi Camera
A simple and robust serial communication protocol. Implementation in C Arduino, C++, Python and Rust.
Outstanding Paper Award on Empirical Resourcefulness in RL
In search of a simple baseline for Deep Reinforcement Learning in locomotion tasks, we propose a model-free open-loop strategy. By leveraging prior knowledge and the elegance of simple oscillators to generate periodic joint motions, it achieves respectable performance in five different locomotion environments, with a number of tunable parameters that is a tiny fraction of the thousands typically required by DRL algorithms. We conduct two additional experiments using open-loop oscillators to identify current shortcomings of these algorithms. Our results show that, compared to the baseline, DRL is more prone to performance degradation when exposed to sensor noise or failure. Furthermore, we demonstrate a successful transfer from simulation to reality using an elastic quadruped, where RL fails without randomization or reward engineering. Overall, the proposed baseline and associated experiments highlight the existing limitations of DRL for robotic applications, provide insights on how to address them, and encourage reflection on the costs of complexity and generality.
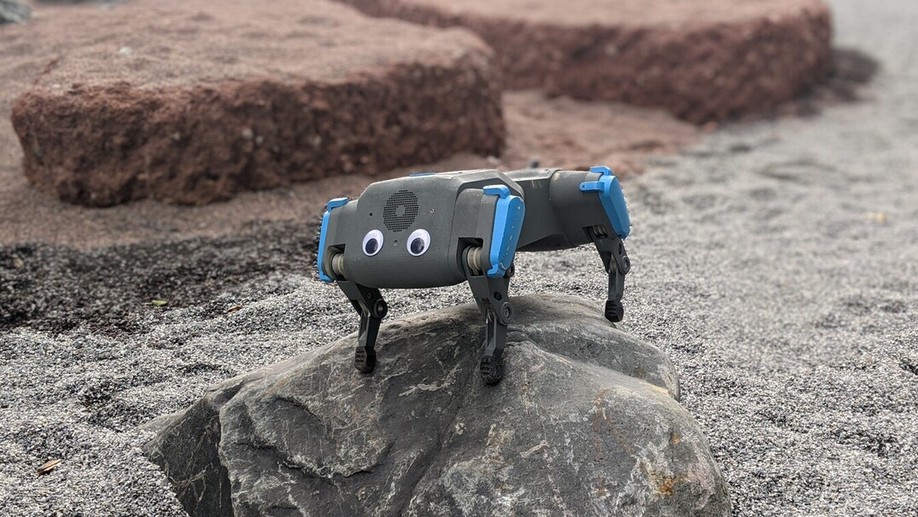
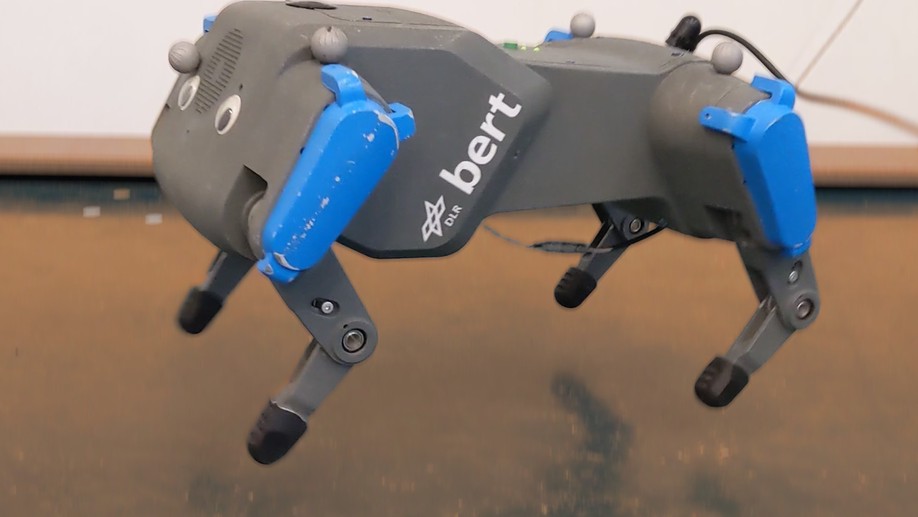
Spring-based actuators in legged locomotion provide energy-efficiency and improved performance, but increase the difficulty of controller design. While previous work has focused on extensive modeling and simulation to find optimal controllers for such systems, we propose to learn model-free controllers directly on the real robot. In our approach, gaits are first synthesized by central pattern generators (CPGs), whose parameters are optimized to quickly obtain an open-loop controller that achieves efficient locomotion. Then, to make this controller more robust and further improve the performance, we use reinforcement learning to close the loop, to learn corrective actions on top of the CPGs. We evaluate the proposed approach on the DLR elastic quadruped bert. Our results in learning trotting and pronking gaits show that exploitation of the spring actuator dynamics emerges naturally from optimizing for dynamic motions, yielding high-performing locomotion, particularly the fastest walking gait recorded on bert, despite being model-free. The whole process takes no more than 1.5 hours on the real robot and results in natural-looking gaits.
This second blog post continues my practical introduction to (deep) reinforcement learning, presenting the main concepts and providing intuitions to understand the more recent Deep RL algorithms.
In a first post (RL102), I started from tabular Q-learning and worked my way up to Deep Q-learning (DQN). In this second post, I continue on to the Soft Actor-Critic (SAC) algorithm and its extensions.
This second post details how I tuned the Soft-Actor Critic (SAC) algorithm to learn as fast as PPO in the context of a massively parallel simulator (thousands of robots simulated in parallel). If you read along, you will learn how to automatically tune SAC for speed (i.e., minimize wall clock time), how to find better action boundaries, and what I tried that didn’t work.
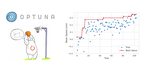
This is the second (and last) post on automatic hyperparameter optimization. In the first part, I introduced the challenges and main components of hyperparameter tuning (samplers, pruners, objective function, …). This second part is about the practical application of this technique with the Optuna library, in a reinforcement learning setting (using the Stable-Baselines3 (SB3) library).